


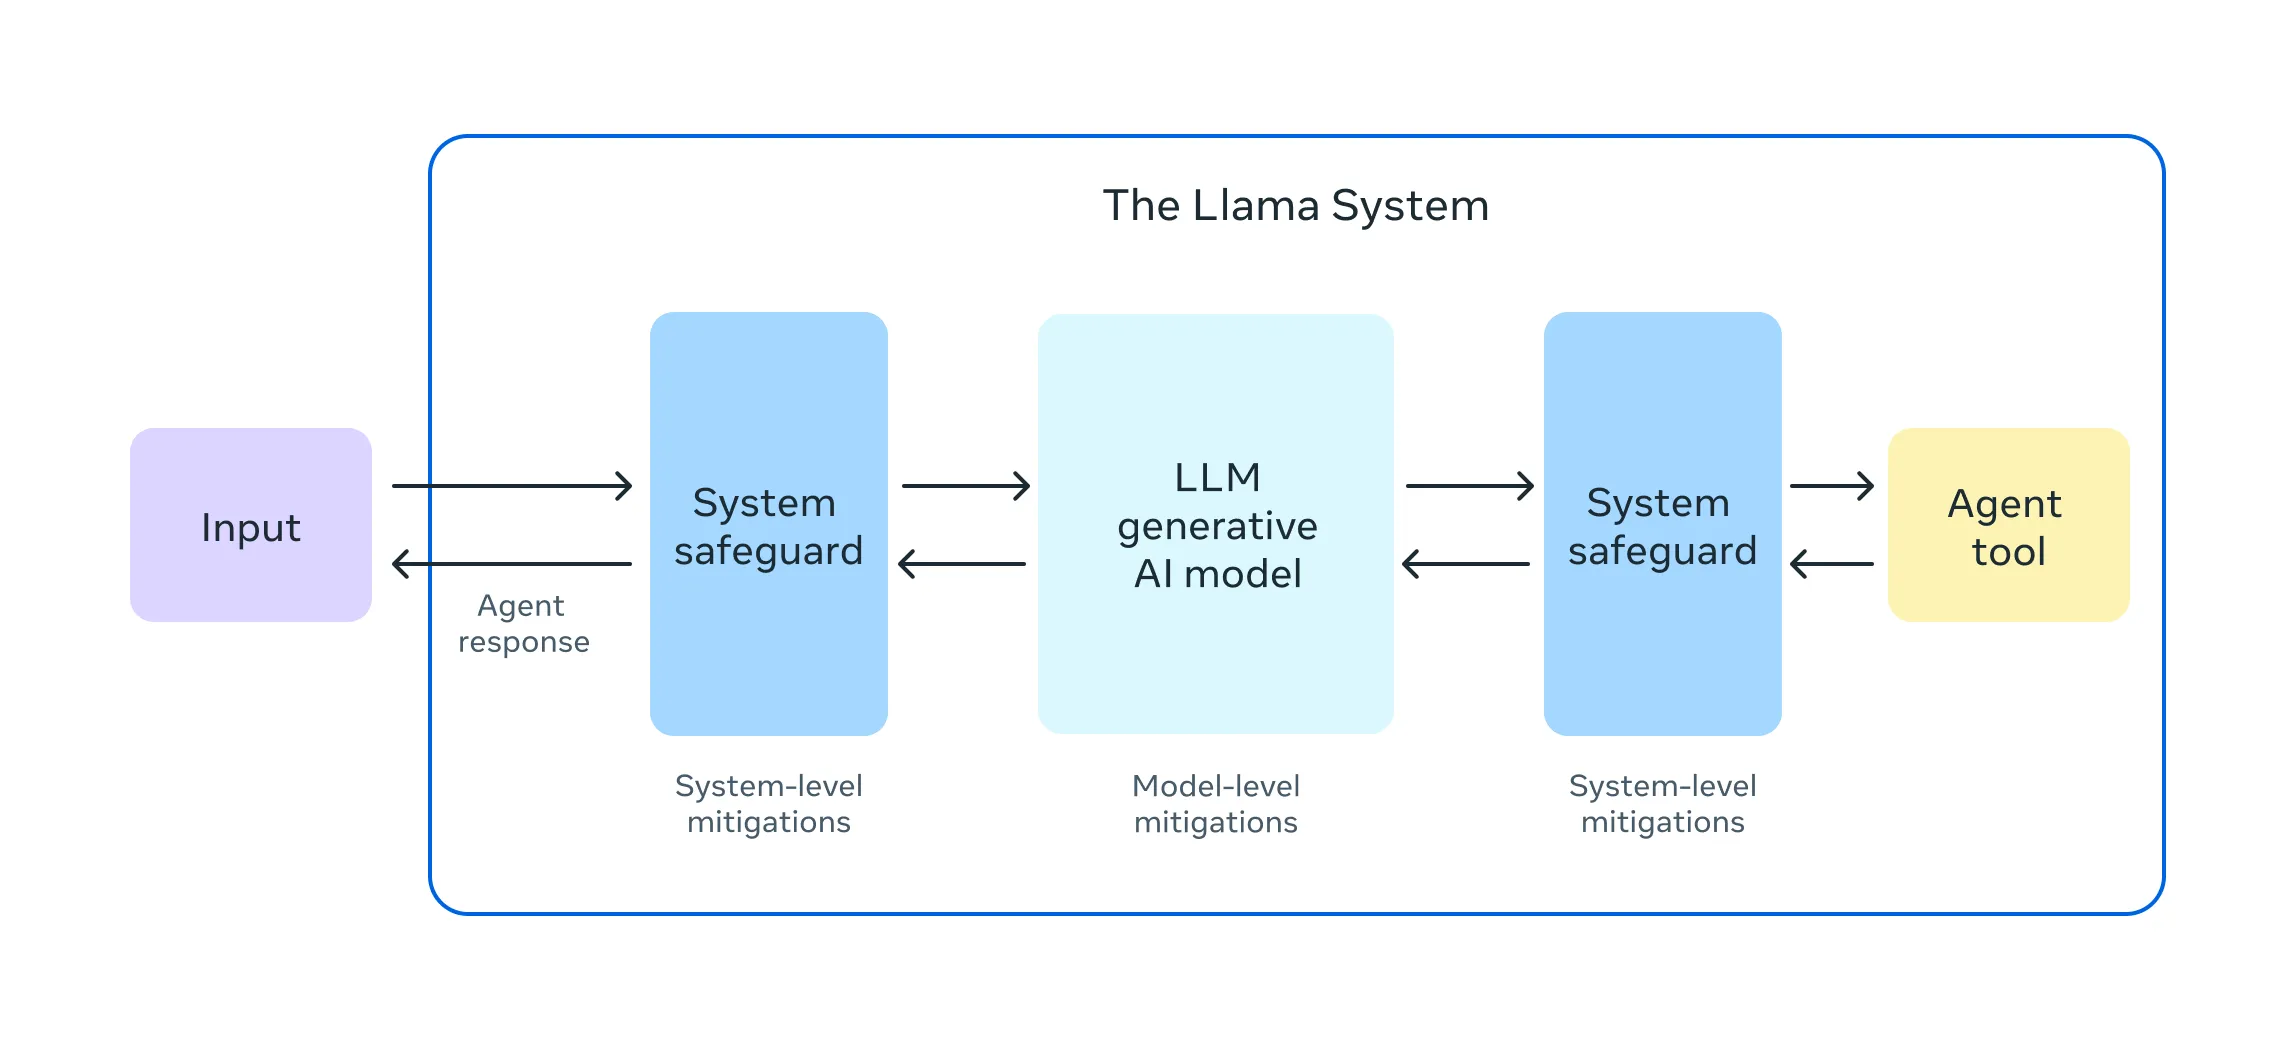
As outlined in our Developer Use Guide, you should deploy appropriate system level safeguards to mitigate safety and security risks of your system. As part of our responsible release approach, we provide open source solutions including:
To get started building with Llama safeguards, head to our ready-to-use recipes on GitHub. We also provide notebooks to tune Llama Guard on your own dataset: GitHub - PurpleLlama, GitHub - Cookbook - Responsible AI.
Fine-tuning an LLM for safety can involve a number of techniques, many of which the research paper on Llama 2 and Llama 3.1 describes in greater depth. You can follow the Meta Llama fine-tuning recipe to get started with finetuning your model for safety. Hugging Face provides further detailed information on how to implement the most commonly used fine-tuning method in their alignment handbook.
To evaluate your model, you could rely on your own private benchmarks. This requires building your own dataset and safety evaluation solution. However, we believe safety evaluations should be standardized to ensure transparency and a consistent, industry-wide approach to safety testing. Such standards are emerging, such as the MLCommons AI Safety v0.5 Proof of Concept.
In the meantime, we recommend using public benchmarking platforms and datasets: