Unifying internal knowledge for faster insights and efficiency
At a glance
Industry
TechnologyUse case
Streamlining knowledge management with an AI assistantGoal
Improve productivity and enable more informed decision-makingLlama version
Llama 4 MaverickDeployment
Hybrid infrastructure with Microsoft Azure AI Foundry and Docker
Empowering digital transformation
Stoque solutions transform business operations through digitization and process automation. Focusing on the financial, graphic and educational markets, their technology reduces operational inefficiencies, streamlines data analysis and eliminates bottlenecks in customer service.
Make internal knowledge instantly accessible
Stoque’s workforce supports multiple technology platforms across several verticals. Retrieving internal information often meant searching through widely dispersed documentation and systems, which weighed on teams’ productivity. Stoque looked to generative AI to synthesize this knowledge and make it rapidly accessible to increase efficiency, improve response times and support more informed decision making.A Llama-enabled productivity assistant
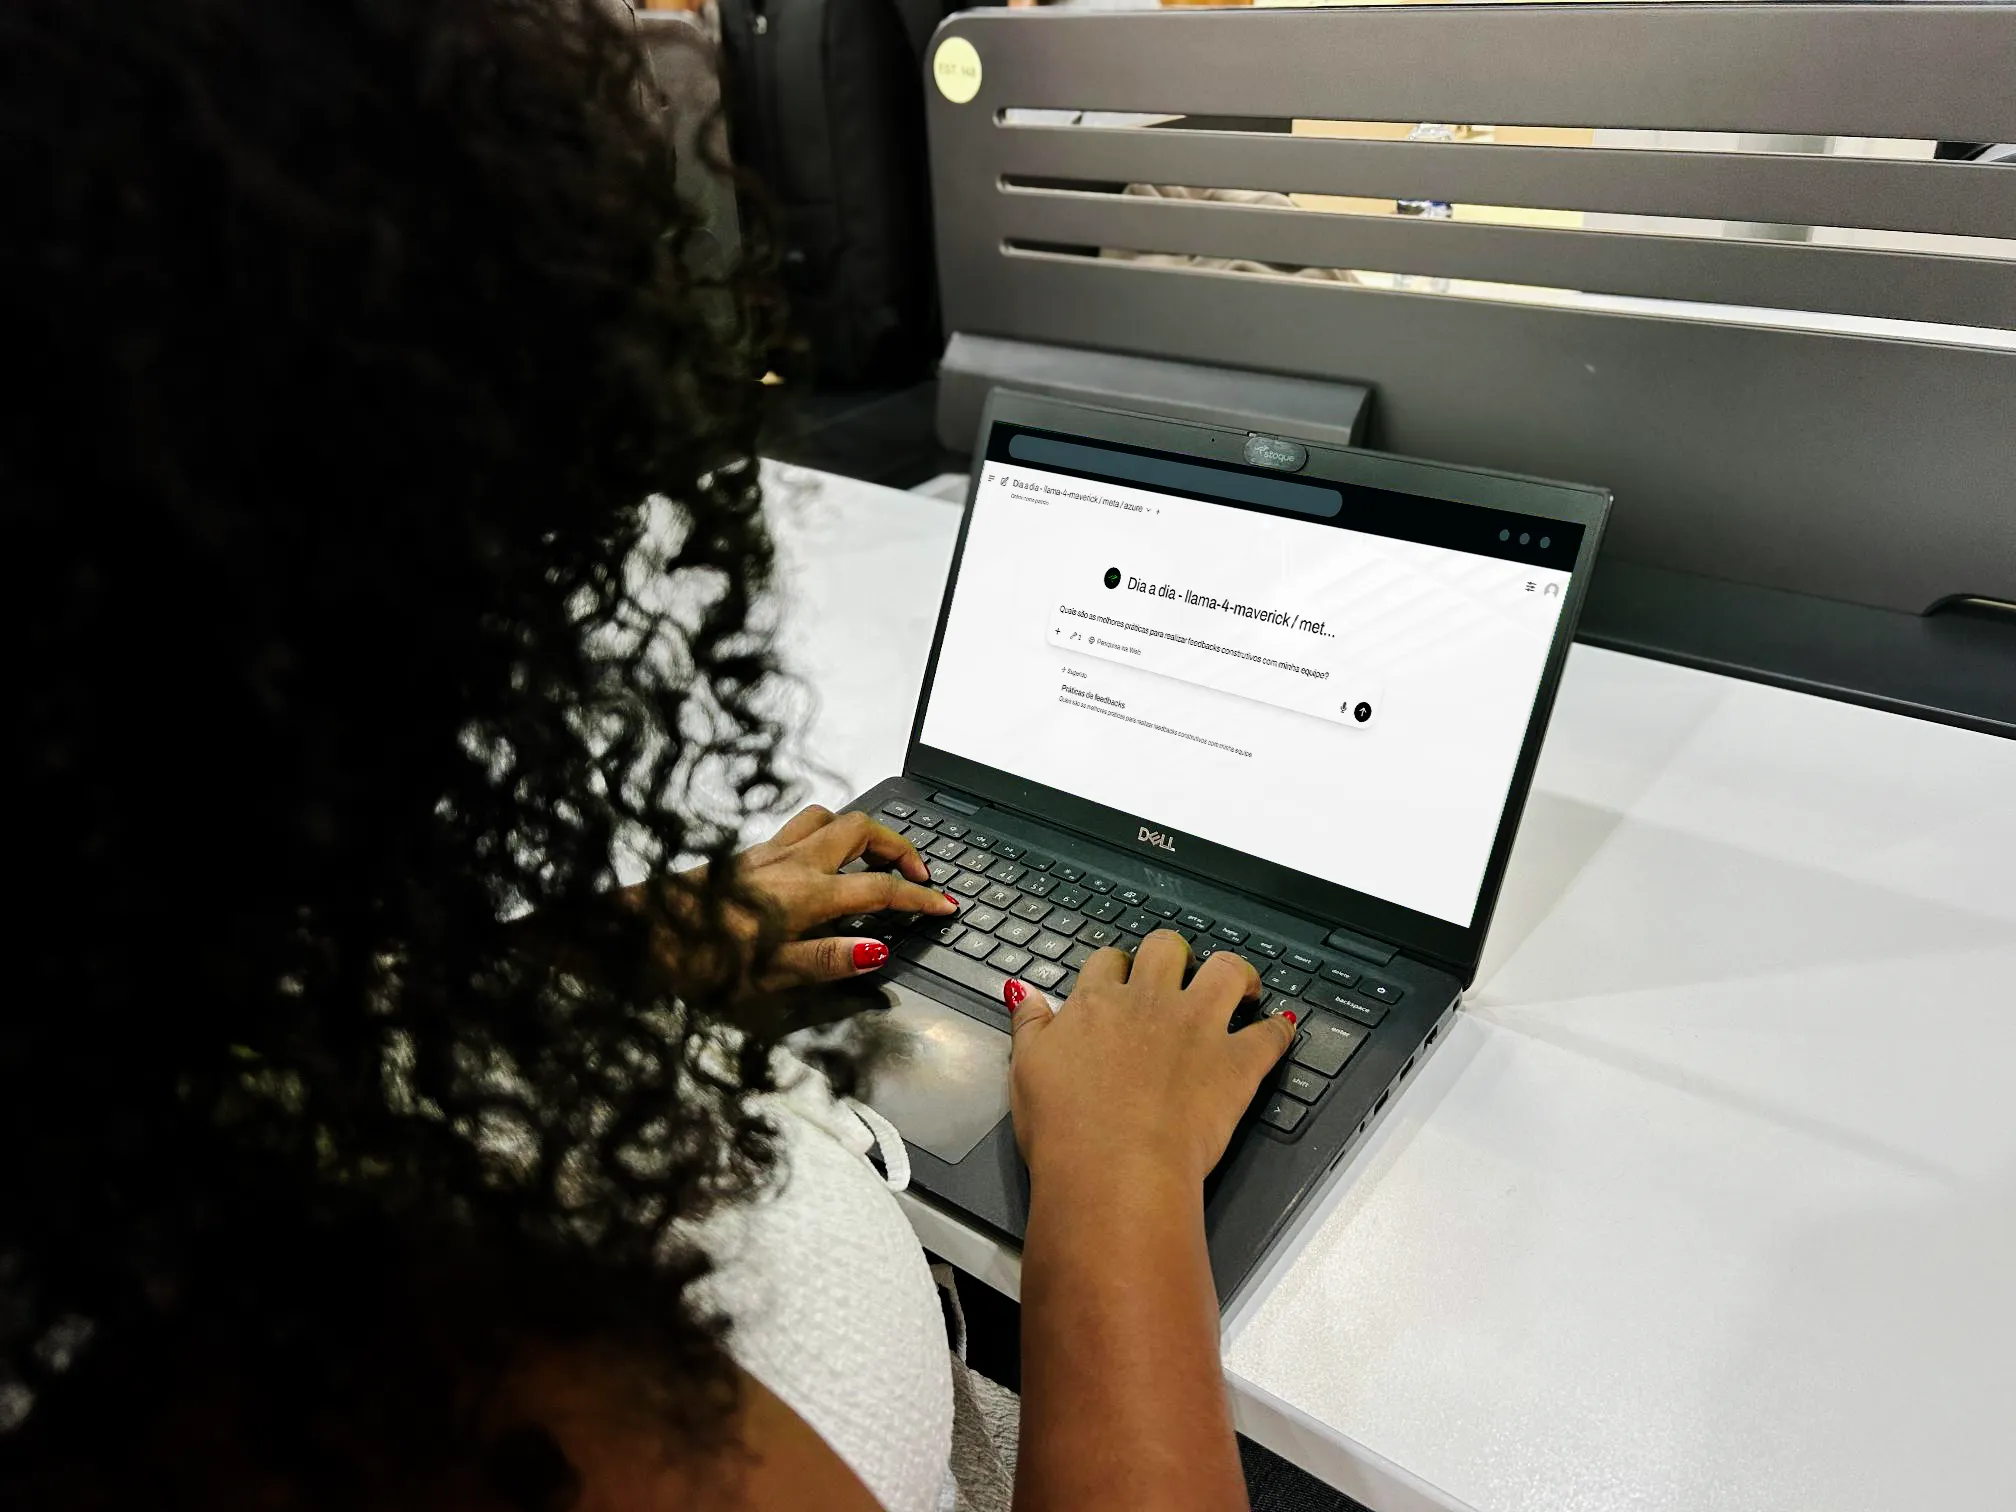
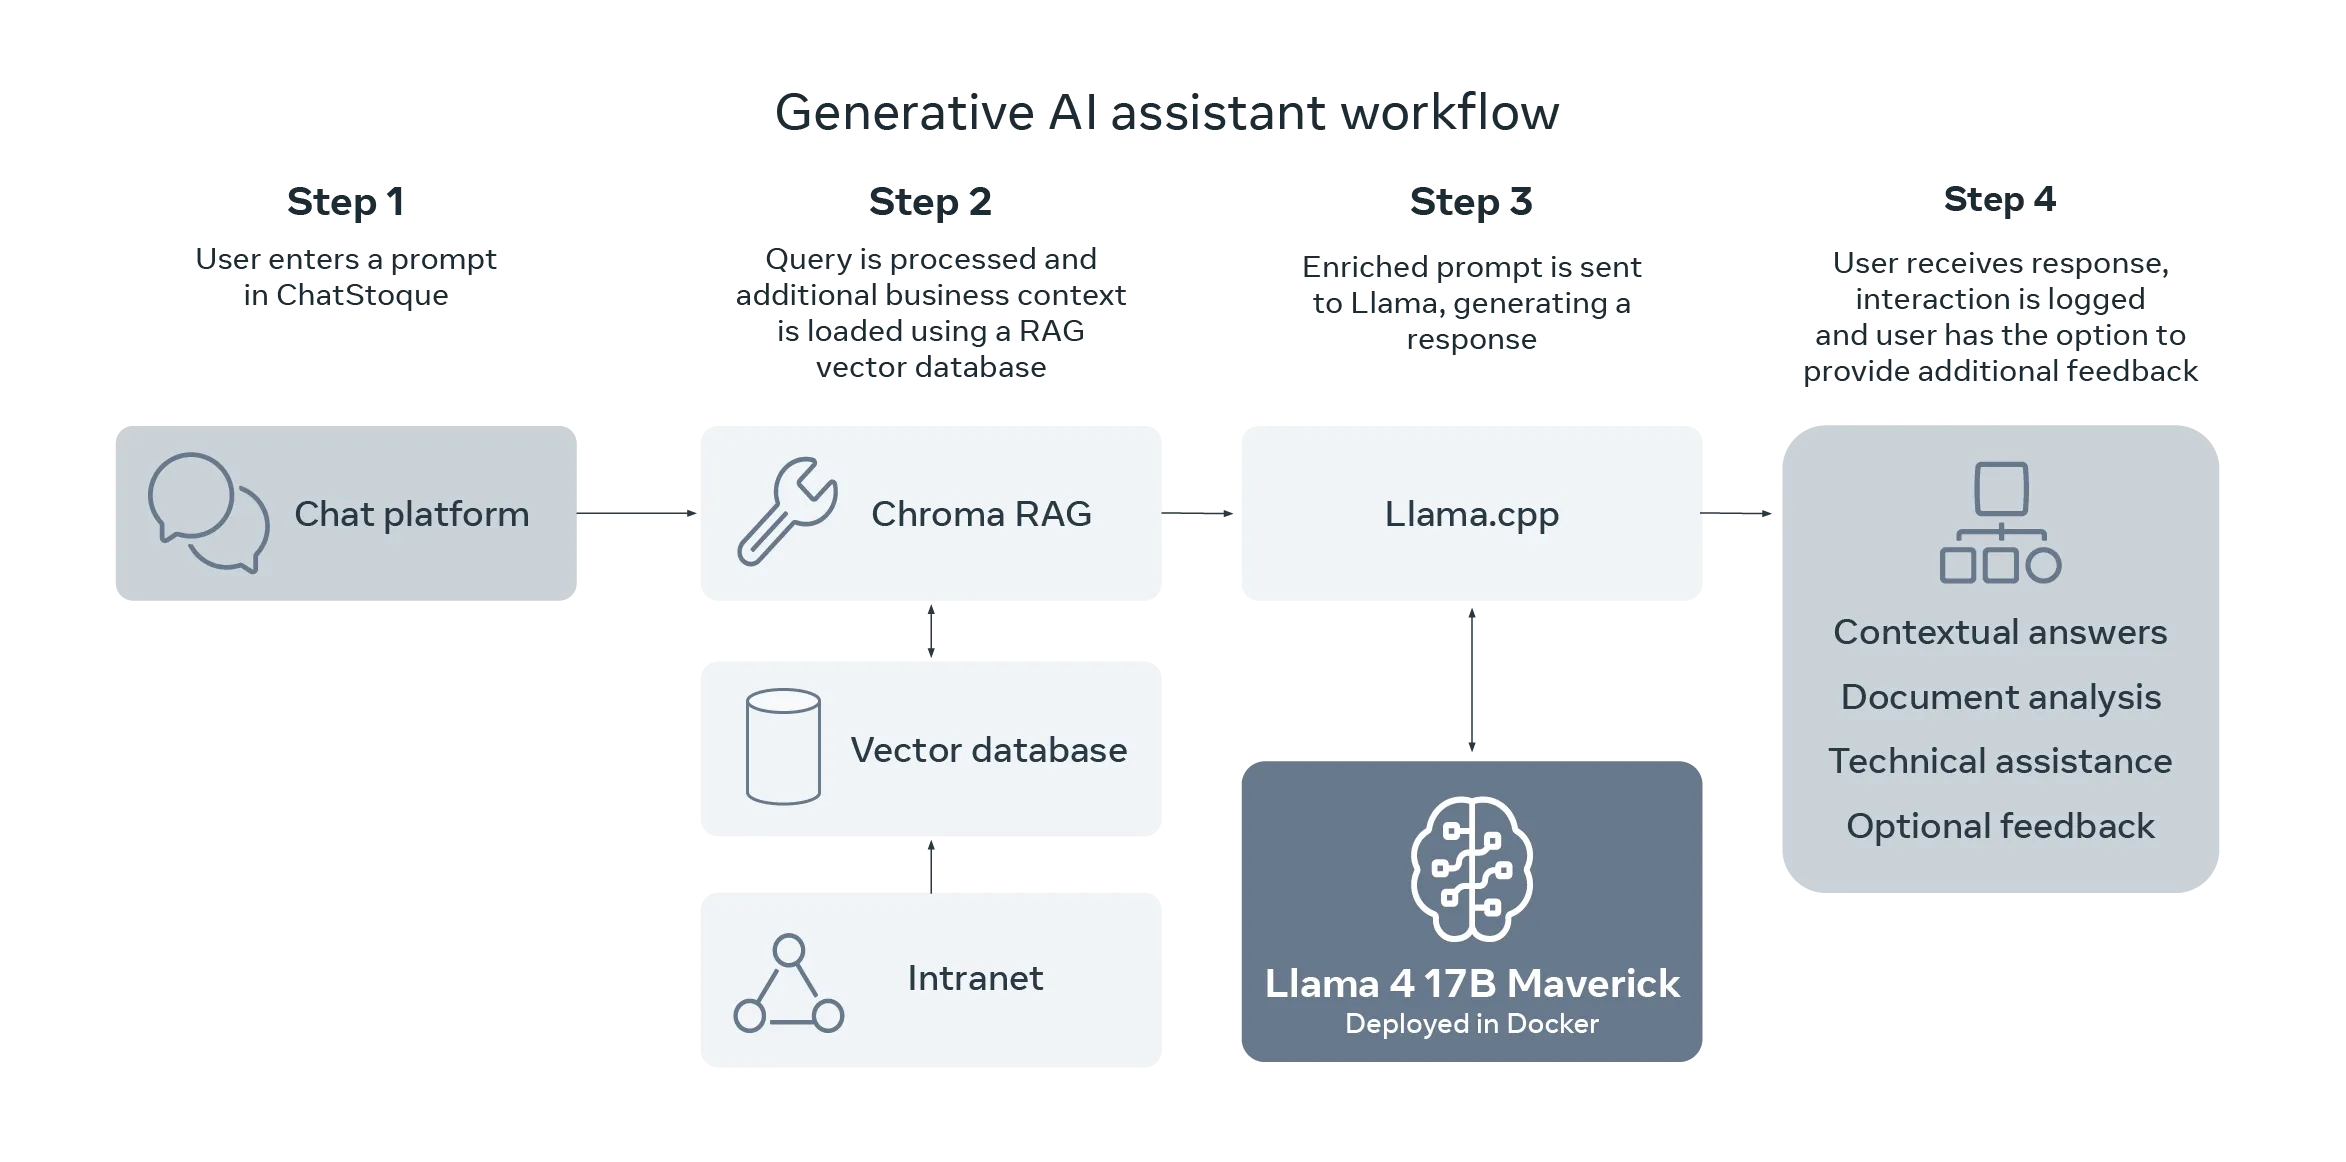
With Llama as their foundation, Stoque developed ChatStoque, an internal AI assistant. Integrated with retrieval-augmented generation (RAG), it can perform contextual queries of internal resources, analyze documents, write summaries and provide technical assistance for development teams. Stoque’s organizational knowledge is available in a single place and team members can enhance their work with insights that leverage historical data and internal best practices.Llama’s open-source model matched Stoque’s priorities for technological independence, ownership of sensitive data and complete freedom to customize the solution. After initial development with proprietary models accessed via API, Stoque pivoted to self-hosted Llama.
Contextualizing responses with RAG and user feedback
Stoque evaluated multiple large language models (LLMs) for ChatStoque, concluding that Llama 4 Maverick offered the best balance between their competing needs. Internal testing showed Llama delivered about 90% of leading commercial models’ performance on natural language tasks, but with roughly 70% lower inference costs. This meant they could scale usage as needed without compromising their IT budget. Their inference stack with llama.cpp improved performance further, with quantization for a lighter runtime and embedded caching to accelerate repeated queries.Using Chroma for the solution’s RAG capabilities, Stoque’s intranet document repository was incorporated into a vector database to support detailed, contextualized responses. When initial accuracy was low, Stoque improved performance by involving users to identify the most critical documents and excerpts. Stoque users also enhance responses using prompt engineering, providing the model with high-quality examples and contextualization by business area.
Accelerated insights for better productivity
ChatStoque gave employees faster, simpler access to internal knowledge while strengthening their digital culture by establishing AI as an ally, rather than a competitor. By eliminating tedious manual searches of dispersed documents and systems, the platform built on Llama allows them to accomplish more work in less time while cutting requests for technical support in half.- 66% faster internal response time for document reading and analysis tasks
- 50% reduction in repetitive queries for technical support