Meta Global AI Developer Hackathon. $1M in prizes.Get notified
LLAMA GUARD 3, LLAMA 3.3 70B, LLAMA 4 SCOUT, LLAMA 4 MAVERICK
Tinfoil
Fast inference in a secure enclave
with less than 10% in performance overheadBillions of tokens processed
with full end-to-end privacyThe only multi-GPU infrastructure
that offers production-ready, verifiably private AI*All results are self-reported and not identifiably repeatable. Generally expected individual results will differ.
CASE STUDY
Keeping data and models private, even when running in the cloud
At a glance
Industry
TechnologyUse case
Model training and inference as a managed cloud serviceGoal
Keep data and models private while maintaining performanceLlama versions
Llama Guard 3, Llama 3.3 70B, Llama 4 Scout, Llama 4 MaverickDeployment
Multiple bare metal cloudsTHEIR STORY
Making AI secure and private
Some of the best AI use cases involve working with private data: personal health information, financial calculations, customer preferences and other data that needs to be kept secure. Tinfoil delivers production-ready private AI by taking the inference or training pipeline and isolating the workflow inside a secure hardware enclave. As a result, people who use Tinfoil can build applications that work securely with all kinds of proprietary or regulated data. Inside the enclave, they can run their choice of open-source and private AI models to generate text, audio, images and video.THEIR GOAL
Maintain privacy in a cloud environment
IT teams often believe the only way to ensure their data remains private is to run models on local hardware. Tinfoil wants to challenge that assumption by delivering the same level of privacy in a multi-tenant, managed cloud.Local deployments require upfront costs to purchase hardware, weeks or months to procure and deploy it, plus ongoing costs to maintain infrastructure. With private AI in the cloud, Tinfoil provides the quick-start convenience, low cost and flexibility of the cloud, plus access to the largest, state-of-the-art generative AI models.
THEIR SOLUTION
Trusted performance with open-source Llama
To deliver private AI in the cloud, Tinfoil runs models on bare-metal NVIDIA GPUs, Intel CPUs and AMD CPUs, leveraging the hardware-level privacy mechanisms of confidential computing. This technology isolates and protects sensitive data from any access, including by administrators. When using Tinfoil, customers have a cryptographically verifiable guarantee that their data cannot be accessed by anyone — not even Tinfoil.Tinfoil has been experimenting with open-source models in the Llama family since its original release. Customers in regulated industries often favor Llama for its open weights and transparent behavior, making it a natural focus for testing. To measure the performance impact of using secure enclaves, Tinfoil ran extensive testing on Llama 3.3 70B, Llama 4 Scout and Llama 4 Maverick both with and without Tinfoil. In most cases, using Tinfoil added less than 10% in performance overhead to the processing time, even when running large models on multiple GPUs.Today, Tinfoil hosts several Llama models to offer a range of open-source options to support different use cases. Llama 3.3 and Llama Guard 3 are available as part of Tinfoil’s self-serve inference offering and are the default models for its private chat. As a dense model, Llama 3.3 70B excels at fine-tuning tasks, giving customers a great option for customizing models. Customers can also choose Llama 4 Scout and Maverick, which offer flexible context lengths, native multimodality and great performance on tool calling tasks. Developers can use the drop-in software development kit (SDK) to leverage Tinfoil’s private inference API in their own application.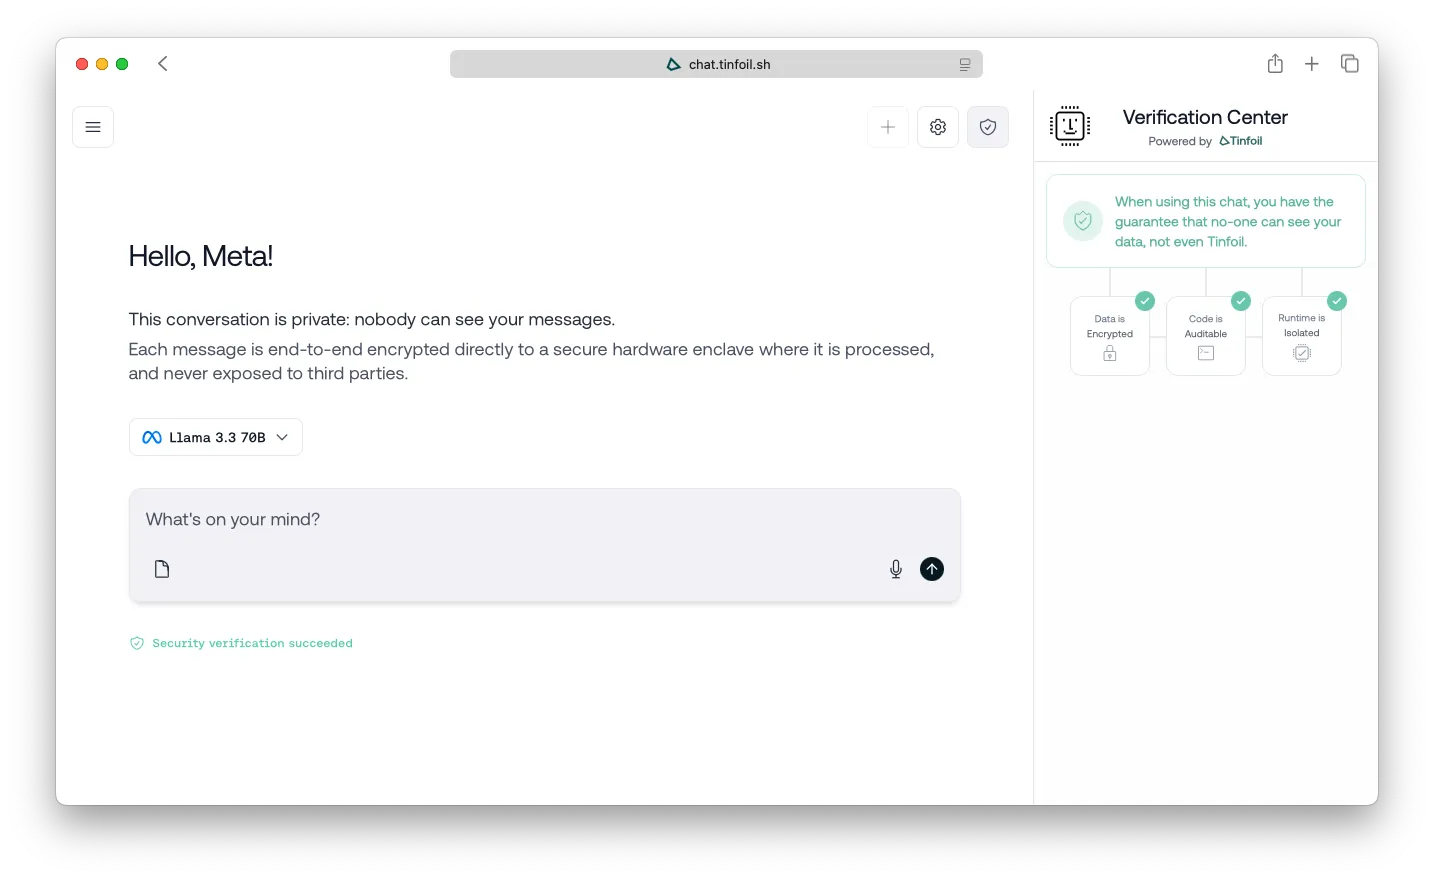 A screenshot of the Tinfoil Chat serving Llama 3.3 70B. The verification center automatically checks to make sure the connection is private and verified, which guarantees that the connection is end-to-end encrypted to a secure hardware enclave.
THEIR APPROACH
A secure, fully auditable environment
With Tinfoil, a cryptographic key is generated inside the secure cloud environment and shared with the person using it. Their data is encrypted and only ever accessible inside the secure enclave. No one else has access — not even an administrator who has privileged access to the machine.Inside the secure environment, Tinfoil uses only open-source code to ensure its stack is fully auditable and adheres to the highest security standards. The solution runs Llama with vLLM to serve production-ready inference workloads at scale. Tinfoil offers private inference endpoints for a variety of Llama models, as well as a browser-based private chat that delivers a secure alternative to popular AI chatbots. Customers can fine-tune Llama models to get a truly personalized model that can write in their own brand voice or integrate proprietary information.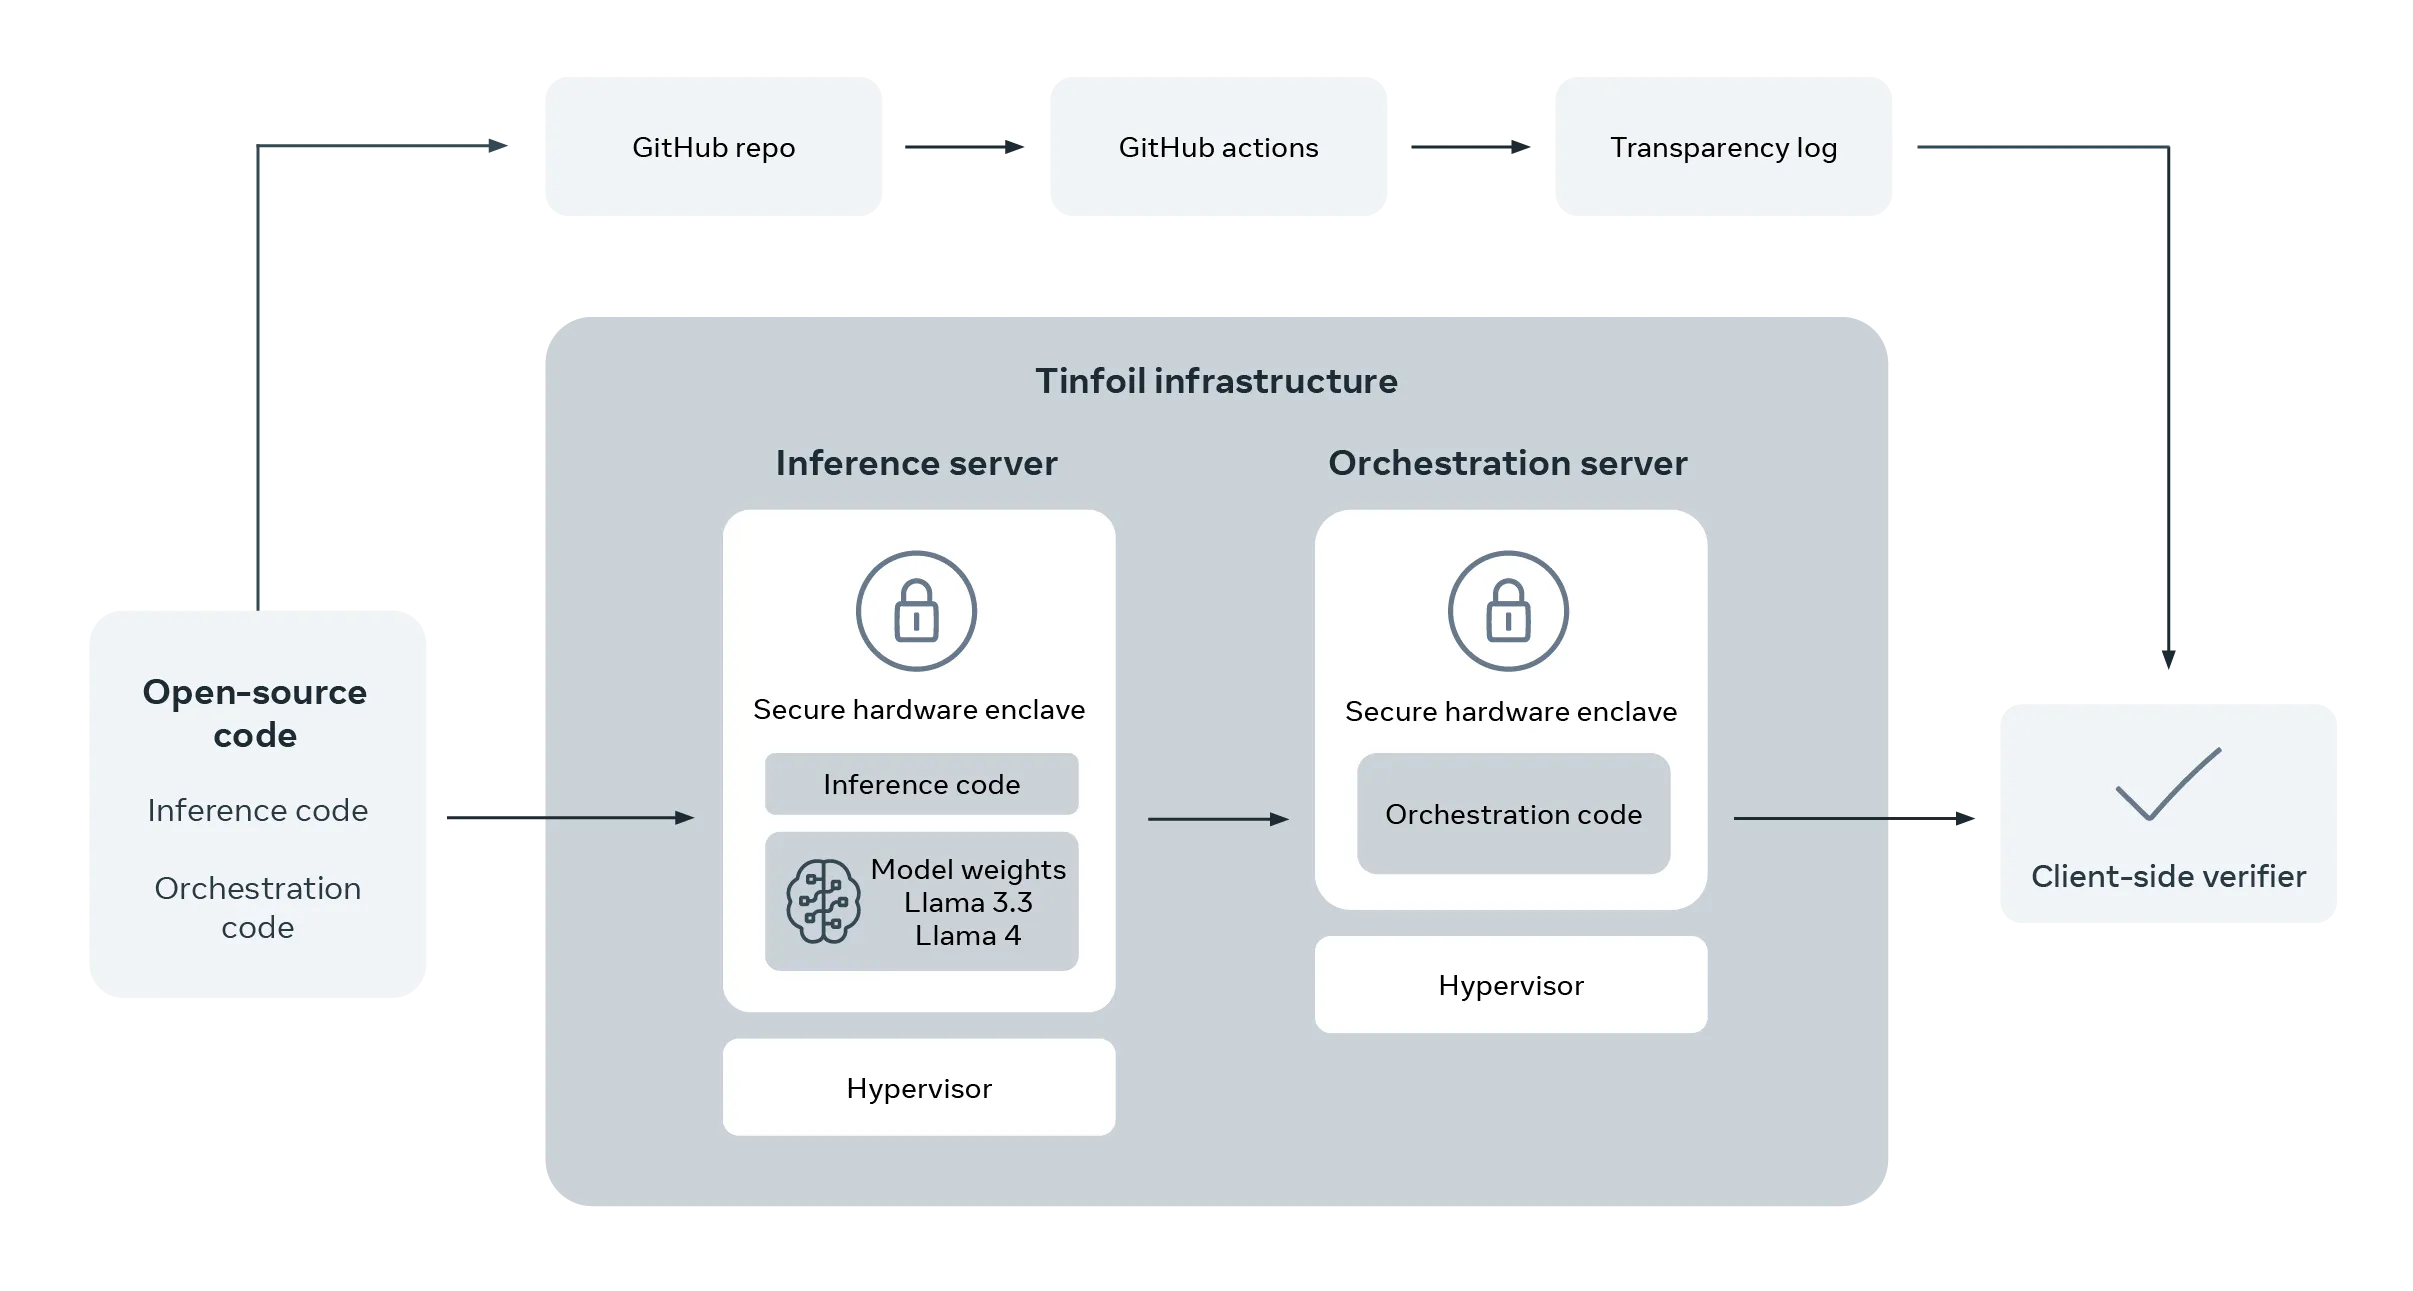 Tinfoil creates a secure hardware enclave in which customers can run inference with full data and model privacy.
THEIR SUCCESS
Billions of tokens processed
Currently, Tinfoil is the only production-ready service that offers verifiably private AI with multi-GPU infrastructure, supporting fast inference on big models. Since launching multi-GPU support, Tinfoil has processed billions of tokens with full end-to-end privacy and can now serve the full, unquantized version of Llama 3.3 70B.Tinfoil says its customers see Llama as their go-to, flexible model family and the backbone of many deployments. Llama 3.3 70B is the most widely used model on Tinfoil’s chat and inference solutions and a consistent favorite for fine-tuning. The team continues to test the Llama 4 family while expanding private chat capabilities to support multimodal processing.
- Fast inference in a secure enclave with less than 10% in performance overhead
- Billions of tokens processed with full end-to-end privacy
- The only multi-GPU infrastructure that offers production-ready, verifiably private AI
“We've found that Llama models are a default choice in mission-critical scenarios where trust is paramount.”
Jules Drean, Co-Founder, Tinfoil
“Llama is the only family of models that can be adapted to a range of applications and deployment scenarios, thanks to a mature open-source ecosystem surrounding the Llama family.”
Jules Drean, Co-Founder, Tinfoil
“Llama continues to be our most popular model among our users and is a go-to for our customers, whether serving their inference or fine-tuning needs.”
Jules Drean, Co-Founder, Tinfoil
Previous slide
Next slide
Start building
Explore more

ConsumerBusiness
Shopify | Llama case studiesShopify uses Llama to generate product pages, localize content, and automate support, helping developers scale workflows and save time.Read more
ConsumerTech
Scribd, INC | Llama case studiesDelivering faster, cheaper and more accurate results with a Llama-powered AI content discovery assistant.Read more
Stay up-to-date
Our latest updates delivered to your inbox
Subscribe to our newsletter to keep up with the latest AI updates, releases and more.