RAGMultimodal
Build Multimodal RAG using Llama 3.2 11BThis blog explores how to build a multimodal RAG system using Llama-3.2-11B-Vision, which combines the strengths of both text and image modalities.Read moreOverview
The architecture of our multimodal RAG system is depicted in the following Mermaid diagram:
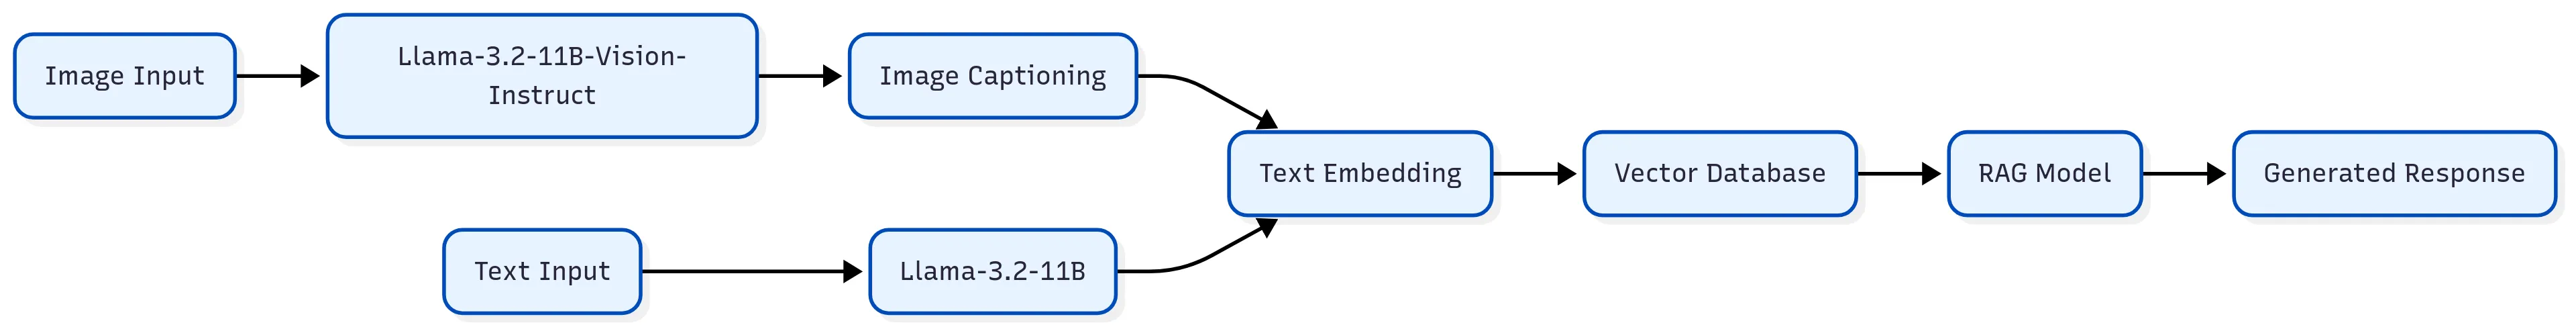
The following process describes how the user interacts with the system:
- Image input: The user provides an image as input to the system.
- Llama-3.2-11B-Vision-Instruct: The image is processed using the Llama-3.2-11B-Vision-Instruct model, which generates a caption that describes the image.
- Text input: The user provides a text query or prompt to the system.
- Llama-3.2-11B: The text input is processed using the Llama-3.2-11B model, which generates a text embedding.
- Text embedding: The image caption and text input are combined to form a text embedding, which is used to retrieve relevant information from the vector database.
- Vector database: The vector database stores a collection of text embeddings that correspond to the knowledge base.
- RAG model: The RAG model uses the retrieved information to generate a response to the user's query.