In this technical blog, we explore how to build a Notebook Llama, a multi-step workflow that converts PDFs to podcasts using various Llama models. We'll dive into the technical implementation details and architecture diagrams, and provide a clear structure for easy understanding.
The Notebook Llama workflow consists of four notebooks, each responsible for a specific task in the PDF-to-podcast conversion process. The workflow is depicted in the following diagram.
The first notebook processes the input PDF using the Llama-3.2-1B-Instruct model. This step involves:
Llama-3.2-1B-Instruct model to extract relevant informationpython# Install required libraries!pip install -r requirements.txt# Load the PDF documentfrom PyPDF2 import PdfReaderpdf_reader = PdfReader('input.pdf')# Preprocess the text datatext = ''for page in pdf_reader.pages:text += page.extract_text()# Use Llama-3.2-1B-Instruct to extract relevant informationfrom transformers import AutoModelForCausalLM, AutoTokenizermodel = AutoModelForCausalLM.from_pretrained('Llama-3.2-1B-Instruct')tokenizer = AutoTokenizer.from_pretrained('Llama-3.2-1B-Instruct')inputs = tokenizer(text, return_tensors='pt')outputs = model.generate(**inputs)
The second notebook takes the processed output from Notebook 1 and generates a podcast transcript using the Llama-3.1-70B-Instruct model.

python# Load the processed text datawith open('processed_text.txt', 'r') as f:text = f.read()# Use Llama-3.1-70B-Instruct to generate the podcast transcriptfrom transformers import AutoModelForCausalLM, AutoTokenizermodel = AutoModelForCausalLM.from_pretrained('Llama-3.1-70B-Instruct')tokenizer = AutoTokenizer.from_pretrained('Llama-3.1-70B-Instruct')inputs = tokenizer(text, return_tensors='pt')outputs = model.generate(**inputs)transcript = tokenizer.decode(outputs[0], skip_special_tokens=True)
The third notebook enhances the podcast transcript by adding dramatization and interruptions using the Llama-3.1-70B-Instruct model.

python# Load the podcast transcriptwith open('transcript.txt', 'r') as f:transcript = f.read()# Use Llama-3.1-8B-Instruct to enhance the transcriptfrom transformers import AutoModelForCausalLM, AutoTokenizermodel = AutoModelForCausalLM.from_pretrained('Llama-3.1-8B-Instruct')tokenizer = AutoTokenizer.from_pretrained('Llama-3.1-8B-Instruct')inputs = tokenizer(transcript, return_tensors='pt')outputs = model.generate(**inputs)enhanced_transcript = tokenizer.decode(outputs[0], skip_special_tokens=True)
The final notebook generates the podcast using enhanced transcript and text-to-speech models: parler-tts/parler-tts-mini-v1 and bark/suno.
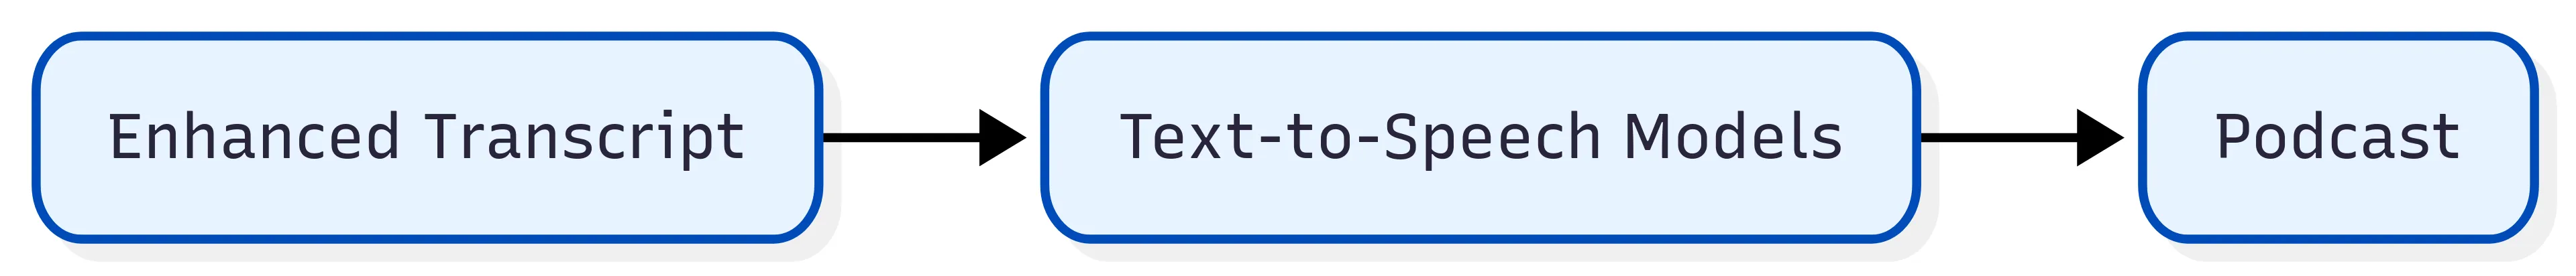
python# Load the enhanced transcriptwith open('enhanced_transcript.txt', 'r') as f:transcript = f.read()# Use text-to-speech models to generate the podcastfrom transformers import AutoModelForTextToWaveform, AutoProcessormodel = AutoModelForTextToWaveform.from_pretrained('parler-tts/parler-tts-mini-v1')processor = AutoProcessor.from_pretrained('parler-tts/parler-tts-mini-v1')inputs = processor(transcript, return_tensors='pt')outputs = model.generate(**inputs)
Building a Notebook Llama is a multi-step process that involves PDF processing, podcast transcript generation, transcript enhancement, and podcast generation using various Llama models. By following this step-by-step guide, you can create your own Notebook Llama workflow and generate high-quality podcasts from PDFs.
NotebookLlama: The official Notebook Llama repository containing the notebooks and code used in this post.
Subscribe to our newsletter to keep up with the latest AI updates, releases and more.